It runs on a computer you can buy at a shop
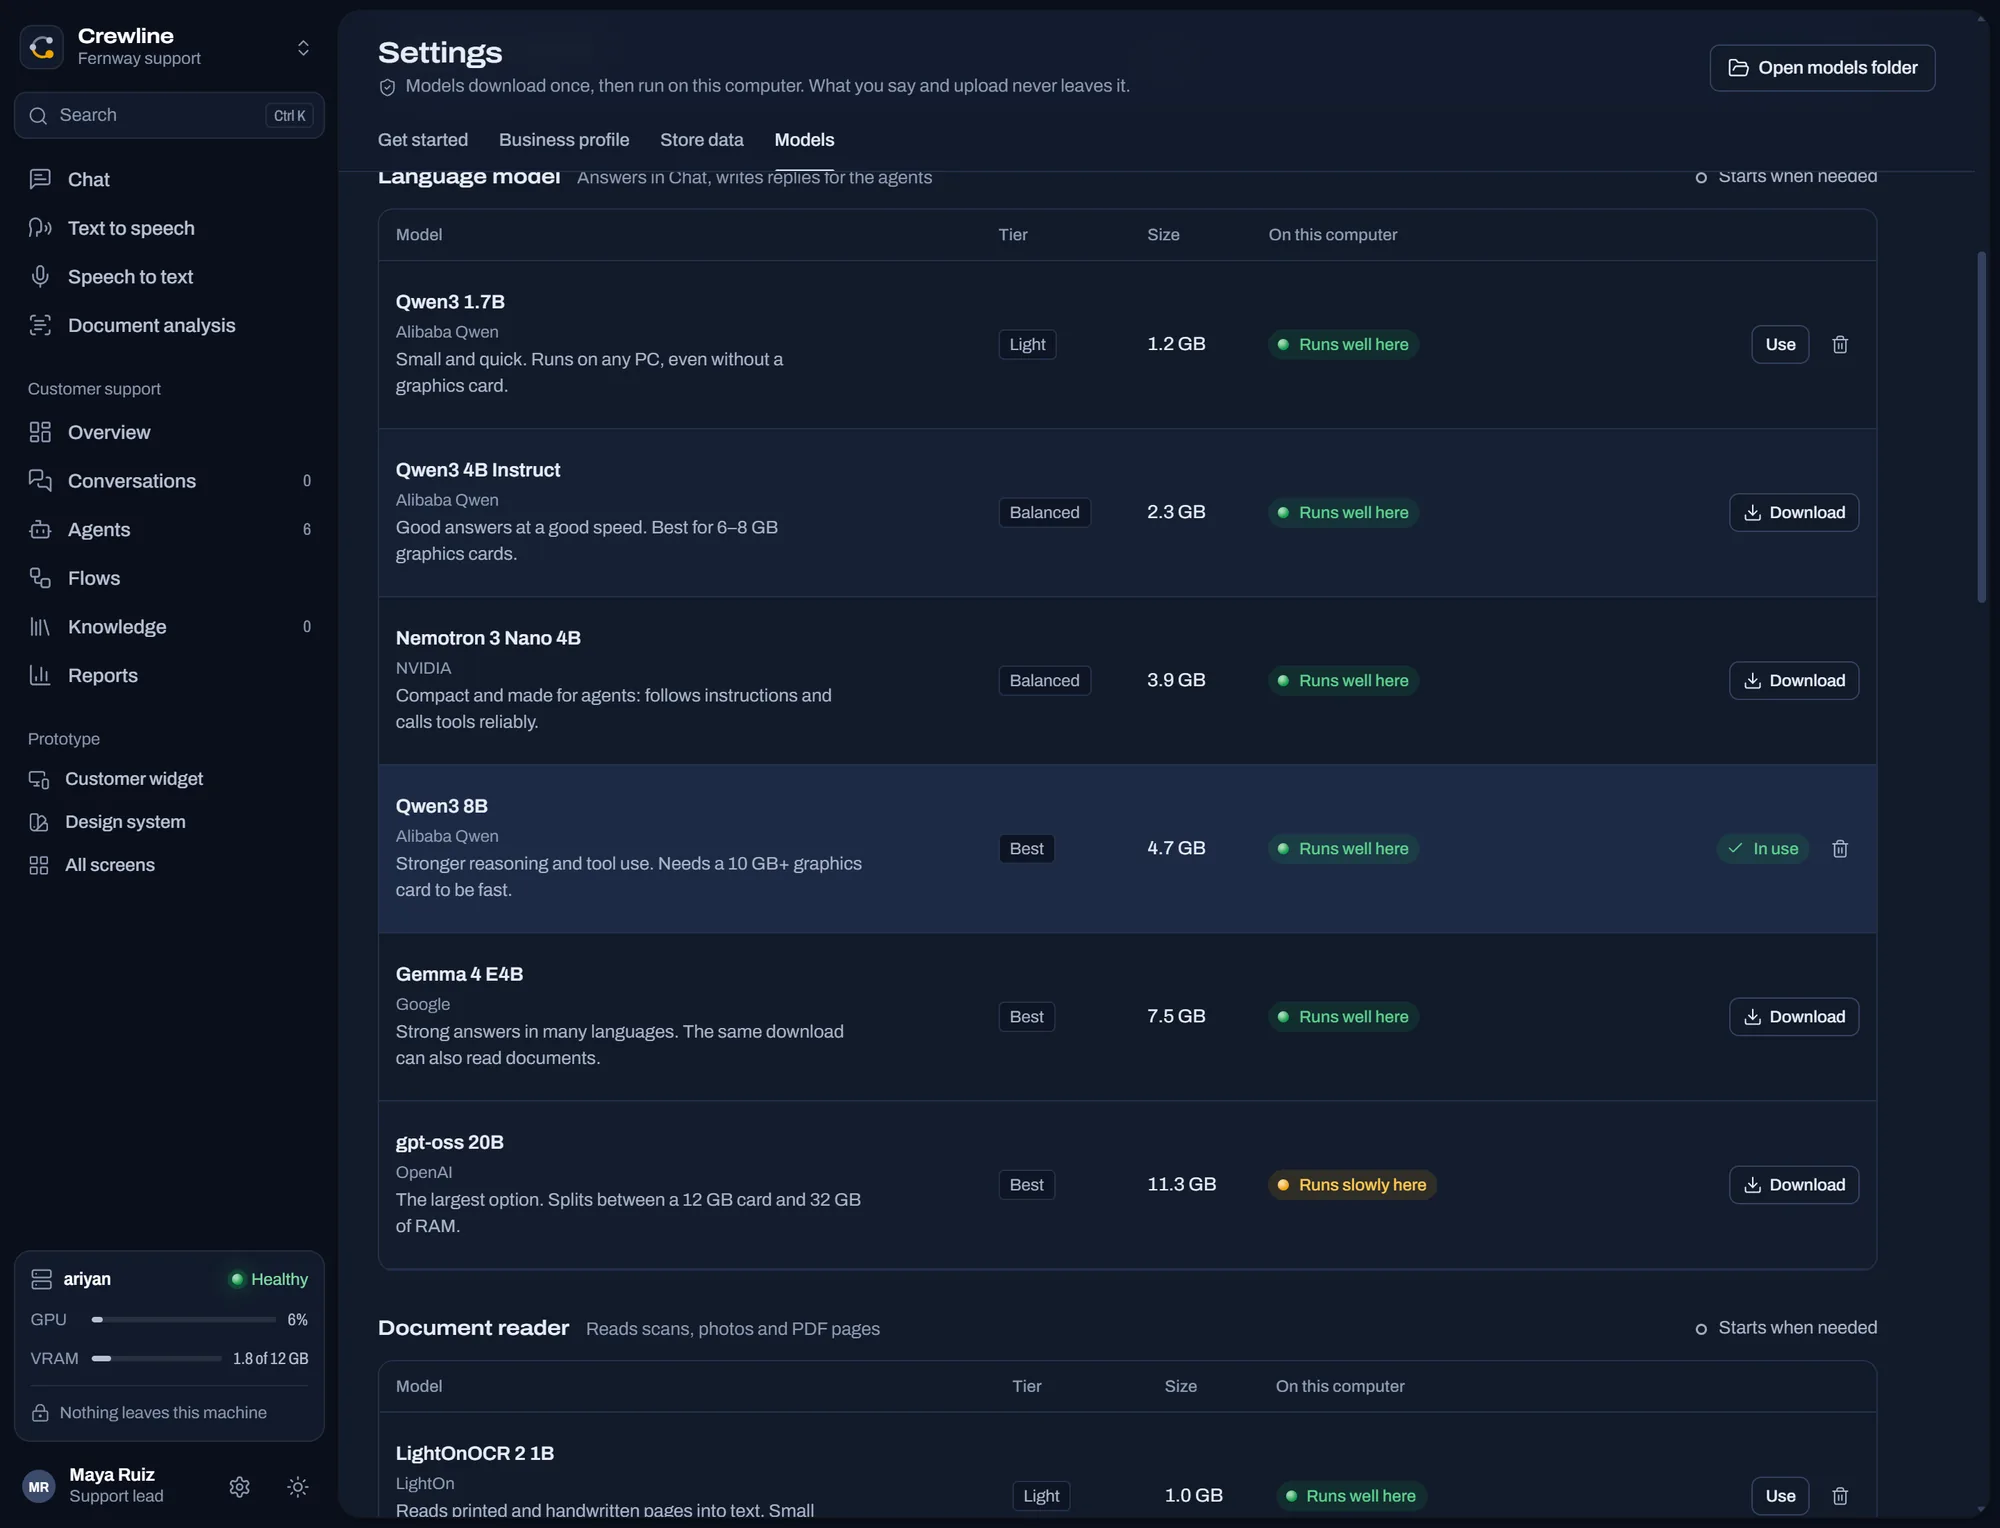
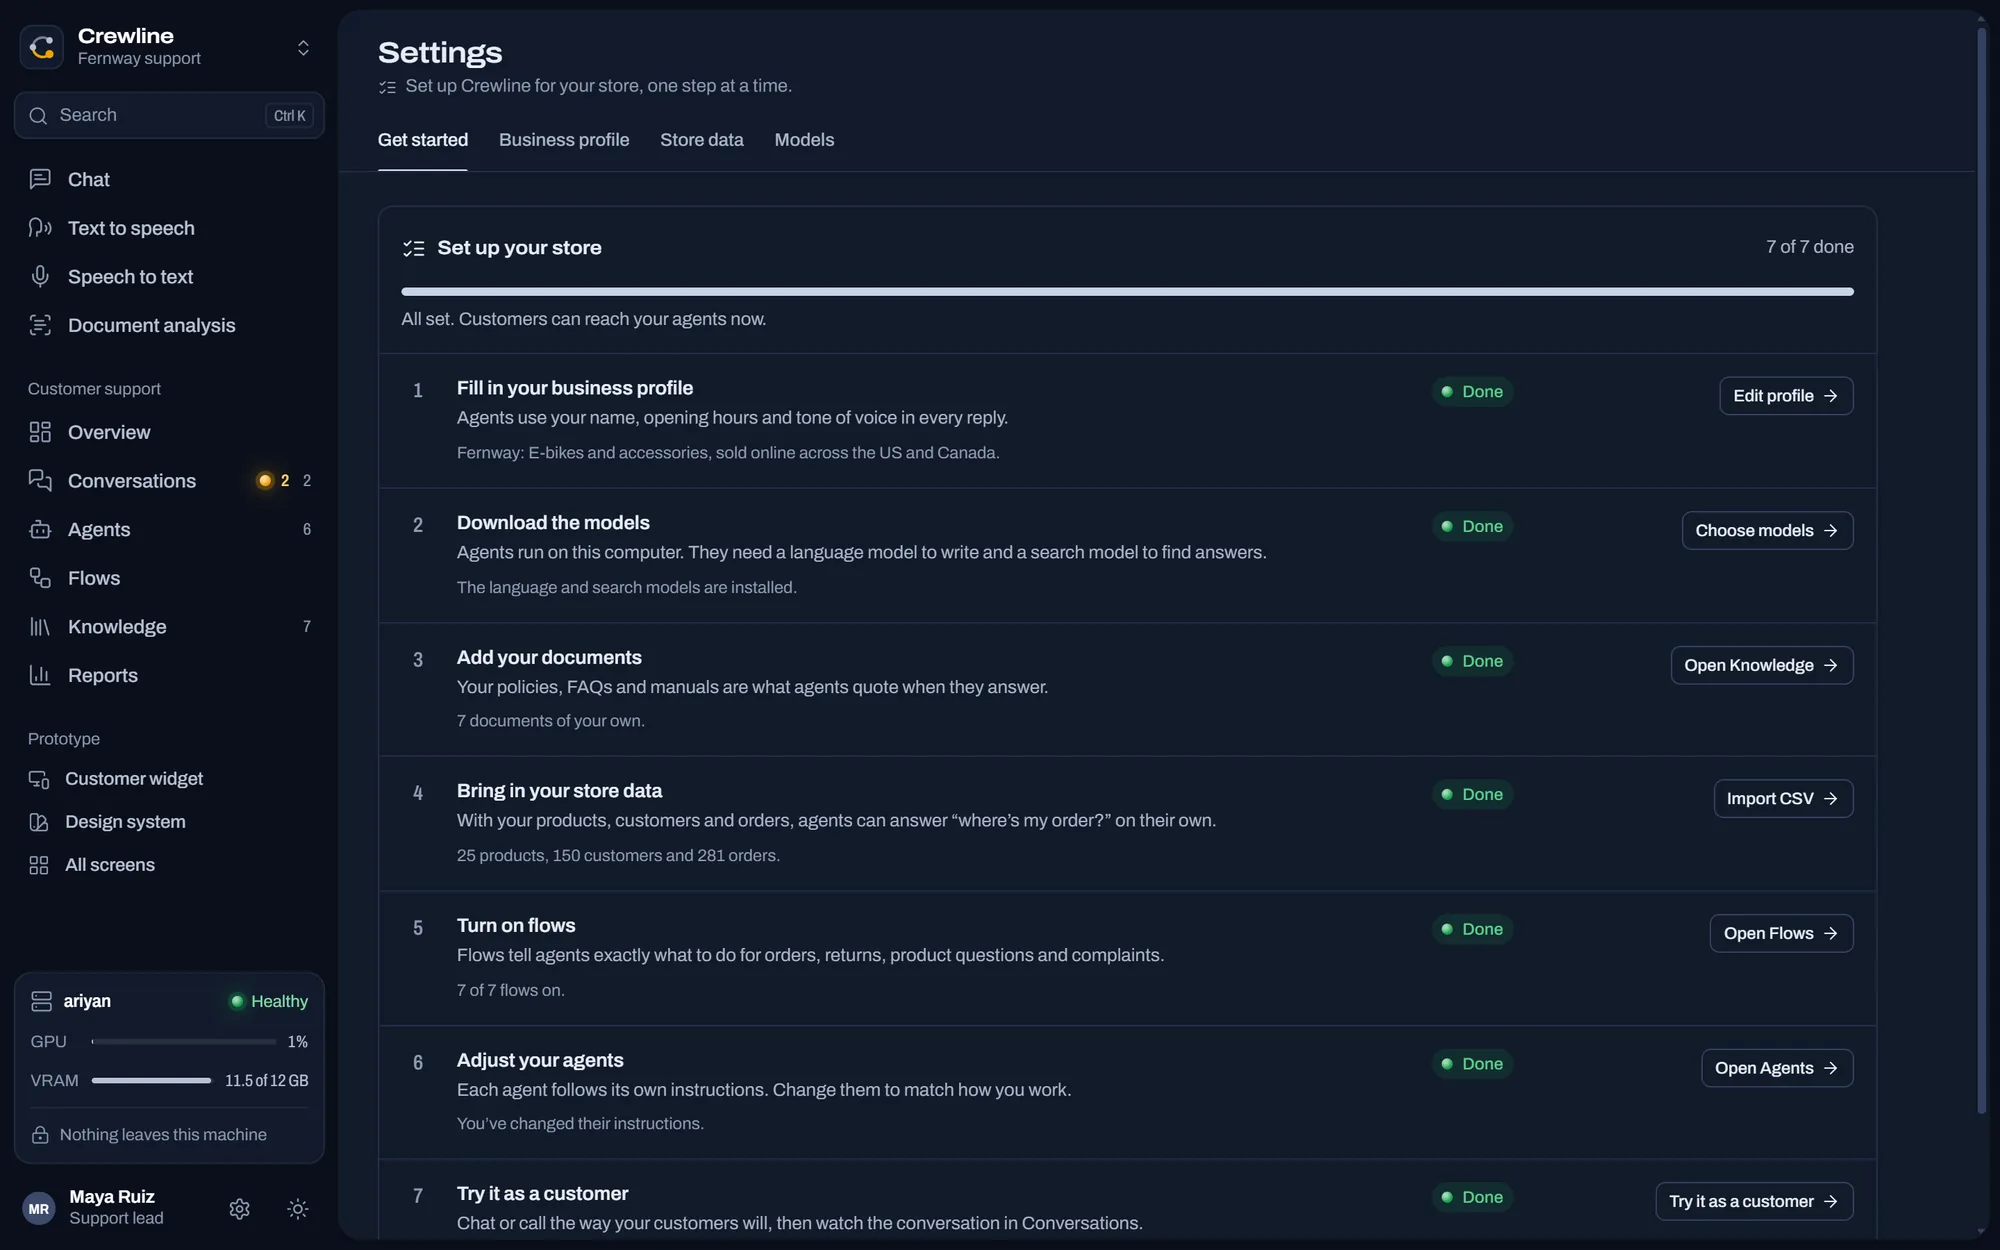
Crewline reads your graphics card and memory, recommends a size and downloads what it needs in one click.
Light: Under 16 GB of memory, no graphics card. Runs on the processor, more slowly.
- Writes
- Qwen3 1.7B, 4 GB memory
- Reads scans
- LightOnOCR 2 1B, 4 GB memory
- Hears
- Parakeet TDT 0.6B, 2 GB memory
- Speaks
- Kokoro, 1 GB memory
Balanced: 16 GB of memory, or a 6 GB graphics card. Needs 6 GB of graphics memory.
- Writes
- Qwen3 4B Instruct, 4 GB card
- Reads scans
- LightOnOCR 2 1B, 2 GB card
- Hears
- Parakeet TDT 0.6B, on the processor
- Speaks
- Kokoro, on the processor
Best: A 10 GB graphics card and 16 GB of memory. Needs 10 GB of graphics memory.
- Writes
- Qwen3 8B, 7 GB card
- Sharpens search
- Qwen3 Reranker 0.6B, 1 GB card
- Sees photos
- Qwen3 VL 2B, optional, 3 GB card
- Speaks
- LFM3-Audio 2B, 3 GB card
What each model does
You can change any of these in Settings. These are the ones the Best tier used on the test day.
| Job | Model | Maker |
|---|---|---|
| Writes replies and chooses flows | Qwen3 8B | Alibaba Qwen |
| Finds passages | EmbeddingGemma 300M | |
| Sharpens the search | Qwen3 Reranker 0.6B | Alibaba Qwen |
| Looks at photos | Qwen3 VL 2B | Alibaba Qwen |
| Hears callers | Parakeet TDT 0.6B | NVIDIA |
| Speaks | LFM3-Audio 2B | Liquid AI |
One graphics card did all of it
The test day ran on an RTX 5070 with 12 GB. Smaller tiers work on any PC, more slowly.
You choose
Settings lists alternatives for each job, including Gemma 4, gpt-oss, Nemotron, Whisper, GLM-OCR and Qwen3-TTS. They download once, through llama.cpp and whisper.cpp.
Put someone on the board
Download for Windows228 MB. Windows 10 or later, 64-bit.